Create Stunning Videos with AI
Turn ideas into stunning videos in seconds with AI.
GPT-Image 2.5 Flare is OpenAI's latest image generation and editing model - the newest member of the GPT-Image line that succeeded DALL-E. It continues the family's defining bet: image generation backed by reasoning. The model plans a composition before drawing it, can search the web to ground facts in the picture, and edits with the same natural-language fluency that made the GPT-Image generation an industry standard.
 Video Generator
 Image Generator
 MCP
Discover selected models from our Best collections, from recent releases to popular image, video, audio and 3D workflows.
 Alibaba
Wan 3.0 Video Prime is the accelerated premium route in Alibaba's Wan 3.0 video line. It is positioned for longer, more complex creative work with multimodal references and native audio. The exact way to access it matters: Wan's product pages, Alibaba Cloud Model Studio, and third-party marketplaces may expose different limits under similar names.
 ByteDance
Seedance 2.5 is ByteDance Seed's next-generation audio-video joint generation model, built on the unified multimodal architecture introduced with Seedance 2.0 and aimed at the thing short-clip models cannot do: telling a complete story in one generation.
 ByteDance
Seedream 5.0 Pro is the flagship tier of ByteDance Seed's fifth-generation image creation family - the model for work that ships rather than drafts. It pairs text-to-image generation and instruction-based editing in one model, accepts up to 14 reference images in a single task, and outputs up to 2K resolution with most generations completing in under 30 seconds.
 ByteDance
Seedance 2.0 is ByteDance's second-generation Seedance video model, released February 12, 2026. It is built on a unified multimodal audio-video joint architecture that handles both generation and editing, accepting up to 9 images, 3 videos, and 3 audio segments plus natural-language instructions in a single request.
 Alibaba
Wan 3.0 is the Alibaba Cloud Tongyi Wanxiang team's newest video generation model, and it attacks the two limits that have defined AI video for the past year: clip length and input flexibility. It generates up to 30 seconds in a single pass, and it is the first mainstream video model to accept office documents - doc, xls, ppt, pdf, and md - as generation input, not just text, images, audio, and video.
MiniMaxMiniMax H3 is MiniMax's open-weight video generation model - and the community reaction told the story faster than any spec sheet: within days of release, tutorials for running it on 8GB of VRAM were circulating alongside ComfyUI integrations on day zero. H3 generates video with synchronized stereo audio in a single pass, up to 15 seconds, at API output up to 2K.
 OpenAI
GPT Image 2.5 Flare is a real OpenAI model with a clear role: produce high-quality images quickly enough for everyday iteration. The “Cheap” suffix is not part of the official model ID. It is a commercial label used by a seller, and it should be treated as a claim about price rather than a separate capability tier.
DeepseekDeepSeek-V4 Pro is the flagship of DeepSeek's V4 series - a 1.6-trillion-parameter MoE with 49B active parameters, a 1M-token context window, and a hybrid attention architecture (CSA + HCA) that cuts long-context compute to a fraction of its predecessors. It is fully open-sourced, served by API, and positioned as open-source infrastructure for long-text processing and agentic applications.
 MiniMax
 Speech 2.8 is MiniMax's speech model released July-August 2026 with one mission: putting the human back into AI voice - capturing vocal texture, breathiness, and speaking pace from just a 10-second sample, with natural tone tags for filled pauses.
 Tencent
Hunyuan 3D 3.1 is Tencent's upgraded 3D generation model, launched globally in January 2026 - the version that took Hunyuan 3D's quality another step with 8-view reconstruction.
 Google
Nano Banana 2 is Google's friendly name for Gemini 3.1 Flash Image. It combines prompt-based image generation with conversational editing, reference images, search grounding, and output from compact sizes up to 4K. It is the workhorse of the Nano Banana family: faster than Pro, more flexible than Lite.
Images, videos, voices, characters, Text and 3D model. All in one place.
Turn ideas into stunning videos in seconds with AI.
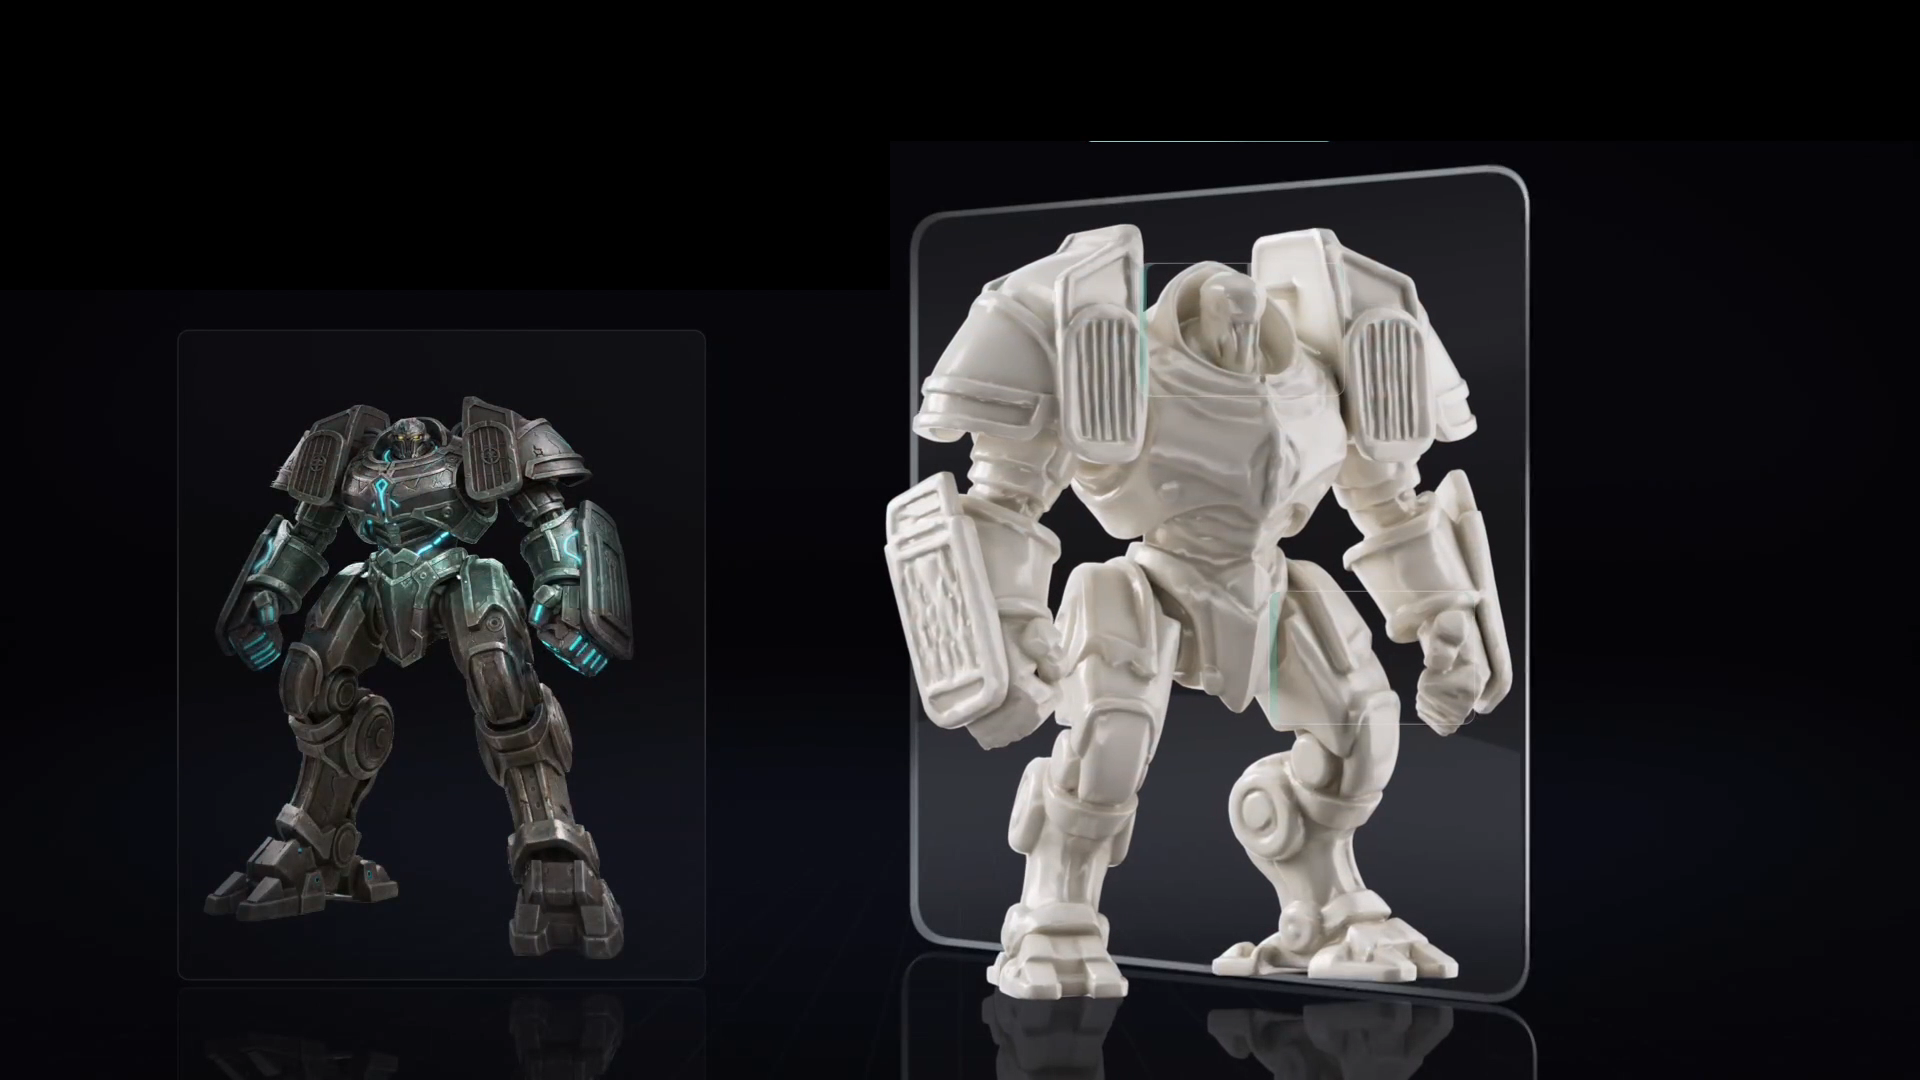
Bring concepts to life with AI-powered 3D creation.
Ask anything, explore everything, and unlock new possibilities with AI.
Go beyond words. Create voices that bring every idea to life.
Design extraordinary characters and bring your wildest ideas to life.
One prompt. Infinite ways to create.
No code, no setup, no 20-minute onboarding video. Pick a template, type what's in your head, and watch it appear. Just create.
Integrate any model with a single API call. Node, Python, or cURL — ship in minutes, not days.
curl https://musespark.ai/api/v1/openapi/task \
  -H "X-API-Key: $MUSESPARK_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
  "model_id": "seedream-5-0-pro",
  "parameters": {
    "prompt": "A cinematic portrait with soft lighting",
    "resolution": "1K",
    "aspect_ratio": "auto",
    "background": "opaque",
    "batch_size": 1
  }
}'
Set your API key and replace example values before running.
Create, edit, and connect ideas in one powerful AI workspace. Turn any inspiration into something extraordinary.
Used by creators, marketers, educators, and enterprise teams worldwide.
I can start with an image, test a few video models and compare the results in my task history. That makes it easier to find the motion that fits a short clip.
One prompt, a few variations, and a much clearer direction for the next design review.
The model pages show the available parameters next to request examples. I can try the same model in Studio before wiring it into my app, then manage the API key in my account.
I use the speech models to explore voiceover drafts before recording the final version. Keeping those experiments beside my other media is useful.
Being able to edit from a reference image helps me keep exploring a visual direction without starting over every time.
Background removal and upscaling cover the small jobs between bigger creative tasks. I can open the tool I need from the same workspace.
A quick way to explore a shape from an image before I take the idea further.
The model catalog makes it easier to compare options for a shot. I check the supported inputs and settings, run a small test in Studio, and return to the result in my assets.
Switching models in Chat lets me compare how they approach the same question. I still check the answers, but it is a useful place to begin.
An image and an audio track are a practical starting point for a talking-character experiment.
I like being able to inspect the request fields before I write the integration. The image, video and audio examples help me understand which inputs change between models.
My prompts, references and generated assets stay close together. I can pick up an earlier experiment instead of trying to reconstruct it from screenshots.
Sharing ideas, stories, and expertise that inspire growth.
Kimi K3.1 Pro, DeepSeek V4.1 Flash, Qwen3.8 Max and GLM-5.3 compared on independent benchmarks, API prices, licenses and US access, as of November 2026.
Read article
We ran Nano Banana 2.1, Nano Banana Pro and Nano Banana 2 Lite through the same two prompts, three times each. Spelling tied, Pro was slightly better on punctuation, and Pro got a ten-item scene right only once in three.
Read articleWe ran Nano Banana 2.1 and Nano Banana 2 through the same prompts and edited one shared image with both. Spelling was a tie; 2.1 kept backgrounds free of invented text and costs about half as much per 1K image.
Read articleKimi AI is Moonshot's chatbot and model family. What K3.1 Pro does well, what it costs, how to call the API from the US, and where it falls short.
Read articleHY4 is bigger, multimodal, and 6.3x the input price of HY3. A developer's guide to specs, benchmarks, USD pricing, and when each model fits.
Read articleGPT Image 2.6 vs 2.5: same token prices and endpoints. What changed: GIF/SVG output, a complexity dial, speed claims, and OpenAI's safety evals.
Read article